
Set up a voice AI interview
Run a voice-based AI interview with real-time transcription.
Voice AI interviews let respondents answer by speaking instead of typing. The AI runs a live voice conversation, asks adaptive follow-up questions, and creates a transcript automatically.
Before you start
Open the survey editor and decide whether you need a standard voice interview or a guided Usability Test. If you plan to control providers or duration, gather those choices before you start building.
Steps
Add a voice AI interview or Usability Test
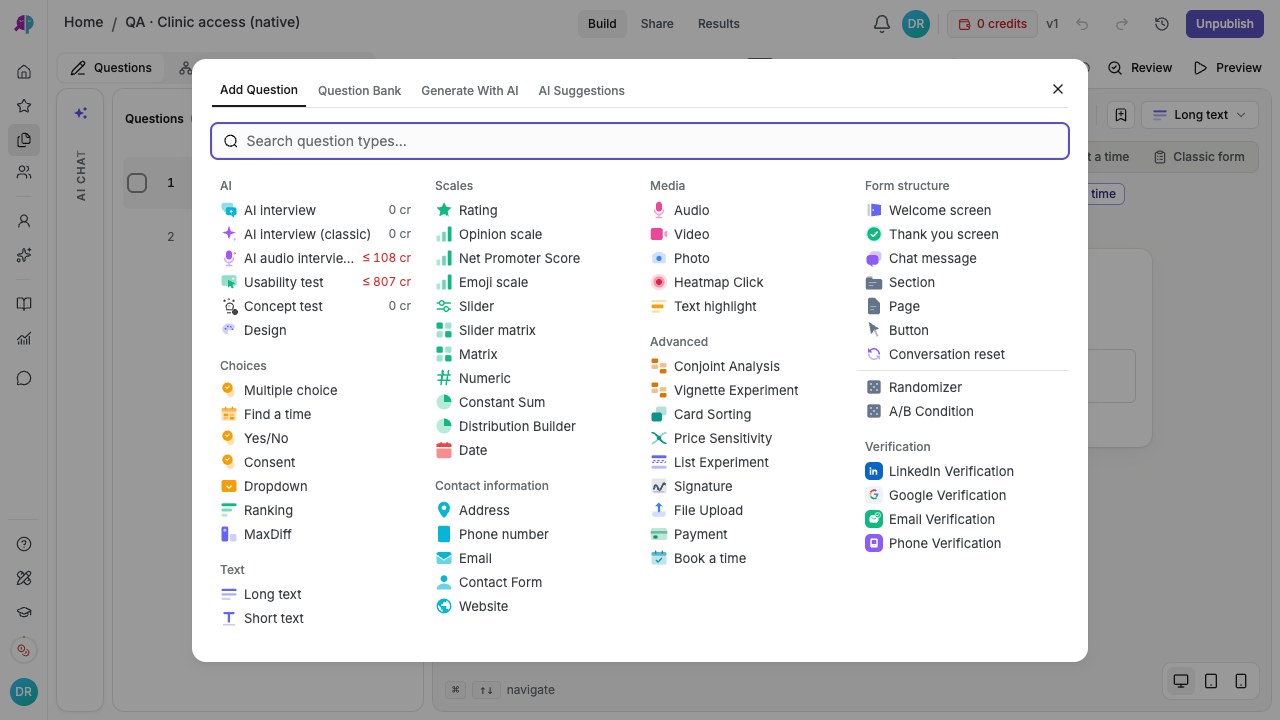
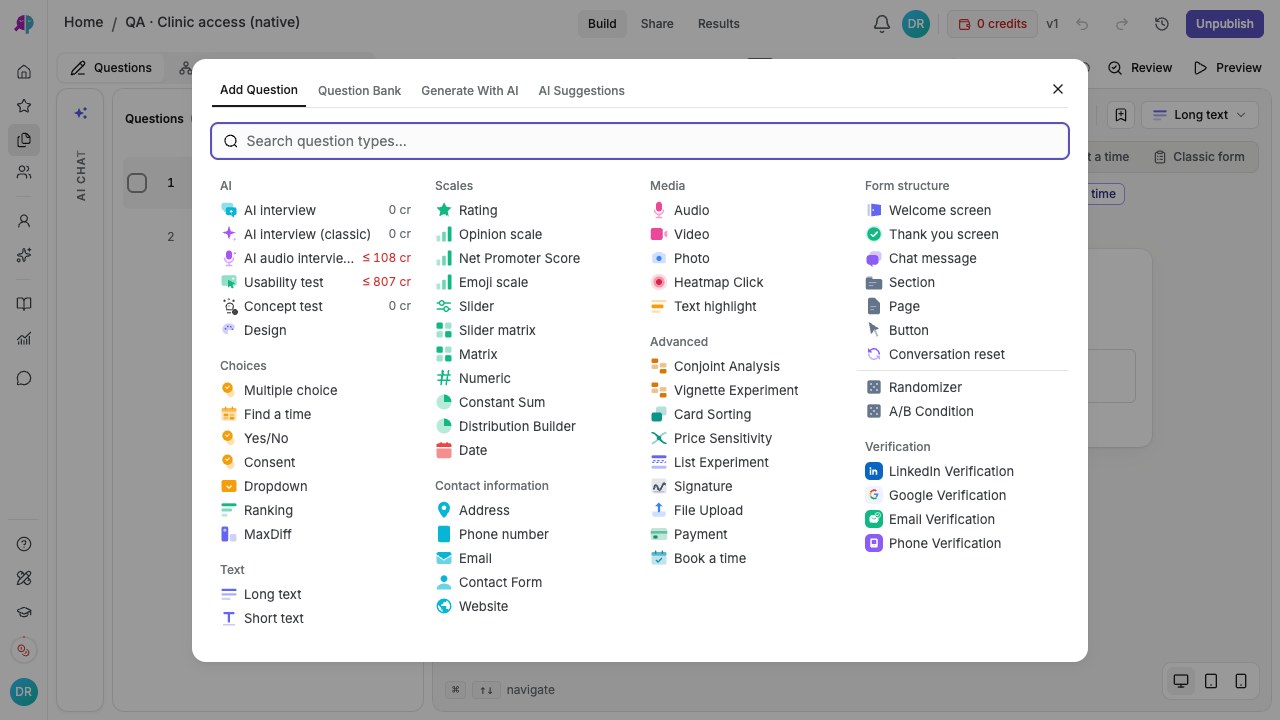
In the survey editor, click Add Question and choose AI interview. Set the interview to Voice. Choose Usability test for guided tasks with screen sharing.English interface · Demo study. Use the controls described in this step.
Set the voice interview options
Set the interview goal and duration. Choose a duration preset or enter a custom duration from 1 to 240 minutes, then review What to find out. Open More settings for Free conversation or Topic guide, interviewer behavior, voice, and the advanced prompt. The default voice setup uses separate speech-to-text, conversation, and text-to-speech providers. Ultra-low latency uses a single realtime model and does not offer What to find out. Existing interviews keep their saved settings.Check the transcript after responses arrive
After an interview, open Results → Responses to read its transcript. If it tracked a What to find out list, review Found out: items are marked Found out, Partly found out, or Not reached, with supporting quotes where available. Check these AI judgments against the transcript. Audio or video recordings are available only when recording was enabled for the session.
Details and limitations
Voice AI interviews remove the need to type. This makes it easier for respondents to share detailed feedback in a natural conversation.
You can use one of two setups: the default chain (separate speech-to-text, AI model, and text-to-speech for maximum flexibility) or Ultra-low latency (a single realtime model for the fastest replies).
Text-to-speech: Choose the provider and voice in the voice settings. Check the available language and cost information before using it. With Ultra-low latency enabled, the realtime model handles speech.
Speech-to-text: Choose the transcription provider in the voice settings. Test domain-specific words, names, and the respondent language in a pilot.
Avatar support: Add a visual AI avatar to voice interviews using Tavus or LemonSlice. Avatars give respondents a face to talk to and can help maintain engagement in longer interviews. Choose from the preset avatars available in the voice settings.
Guided usability testing: Voice AI interviews support a guided usability testing mode. In this mode, respondents complete step-by-step tasks on a website or app while the AI moderator observes through screen sharing. You can configure task scenarios, time budgets, warmup tasks, think-aloud prompts, and counterbalanced task ordering. See the usability testing guide for full setup details.
Pricing: Voice interviews consume AI credits according to the selected providers and interview duration. Each voice interview’s setup shows about how many credits one interview costs and how many interviews your balance covers, with Buy credits when that is fewer than ten. The publish window and the Share tab of a published survey show the same coverage. On a shared survey, the estimate uses the rate of the owner whose credits pay for it. Review the cost before publishing.
Built-in audio enhancement (ai-coustics) applies voice focus and speaker isolation to improve transcription accuracy in noisy environments. Short noises and one-word interjections like coughs or "mm-hm" do not cut the interviewer off.
Transcripts are generated automatically for every voice interview, so you can analyze audio responses more easily.
Run a device check before recruiting. Complete a short voice pilot on the devices and in the languages your participants will use. Check microphone permission, whether both sides can hear each other, transcript accuracy, and any recording you need. A text Preview alone does not verify voice capture. If audio stops, follow microphone, camera, and screen-sharing troubleshooting.
Choose what to find out: below the goal, use Suggest from the goal or Write my own. New voice questions can suggest a list after you enter a goal. Edit the wording, use + Add for another item, and move the most important items to the top. The list holds up to 12 items. Suggest again replaces the list; removing every item turns tracking off.
Fit the list to the time: the editor estimates how many items fit the selected duration and labels extra items if time allows. Shorten the list, reorder priorities, or use the offered Make it … min button when a longer preset fits. This is planning guidance, not a promise that every item will be covered. In Results → Summary, What we found out summarizes the interviews that tracked each item; see report interpretation.
Check the result
You have a goal, duration, voice, and prioritized What to find out list where supported. Pilot the interview, then check its transcript and tracked findings in Results. Saved recordings require recording to be enabled.
If something goes wrong
If you cannot choose a voice, check whether Ultra-low latency is turned on. That mode uses a single realtime model and does not include voice choice.